Seedera
Request dataScalable data infrastructure for world models.
Engine-generated environments, with camera pose on every frame and ground-truth layers on sampled frames.
Request dataSeed 1303
Layout
Built by a team from
Vision Pro
ByteDance
Pose6-DoFcamera position and rotation, every frame
Depth16-bitwhole centimetres, planar
Segmentation9 classessky to props
NormalsWorld space8-bit RGB
Depth, segmentation and normals are produced for sampled frames.
One frame, four layers
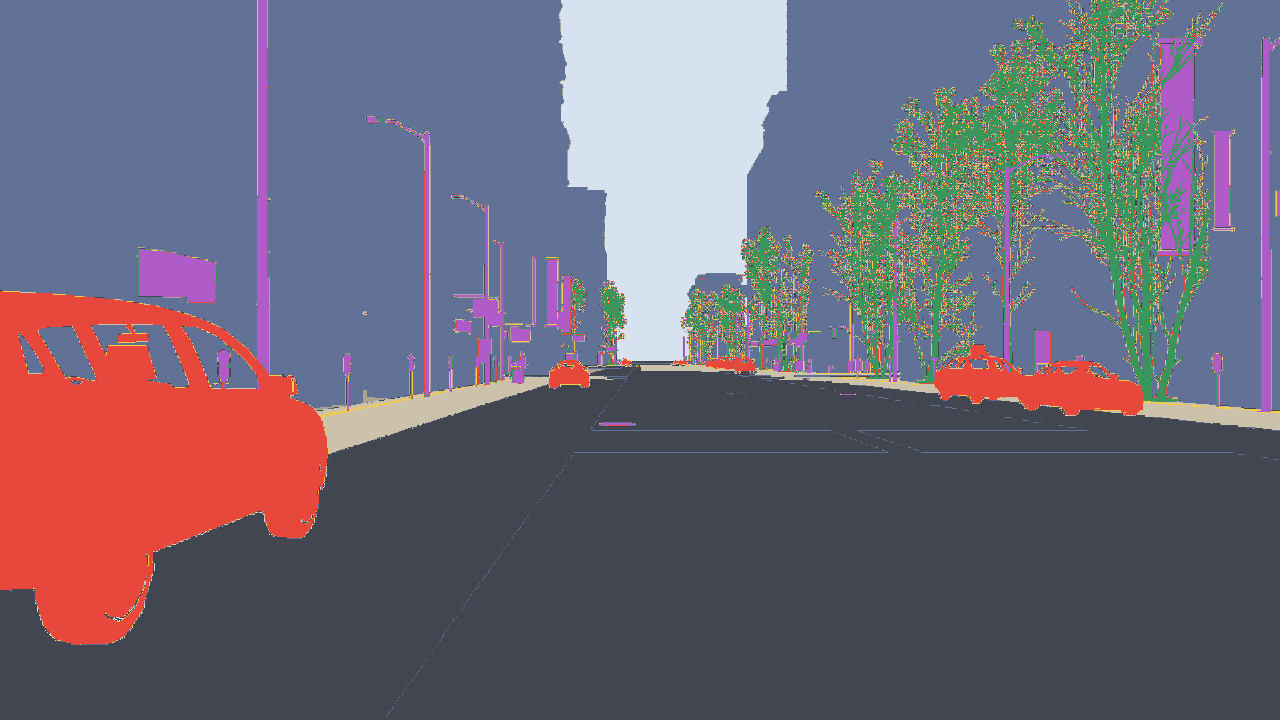
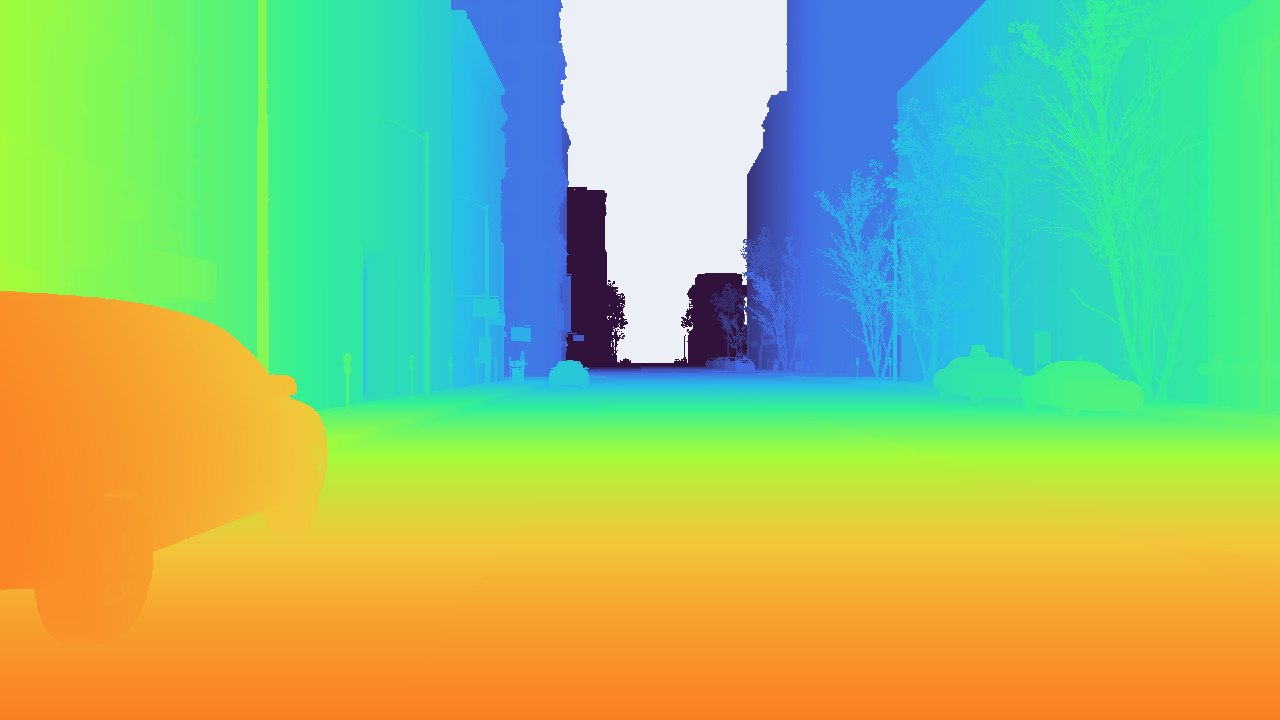
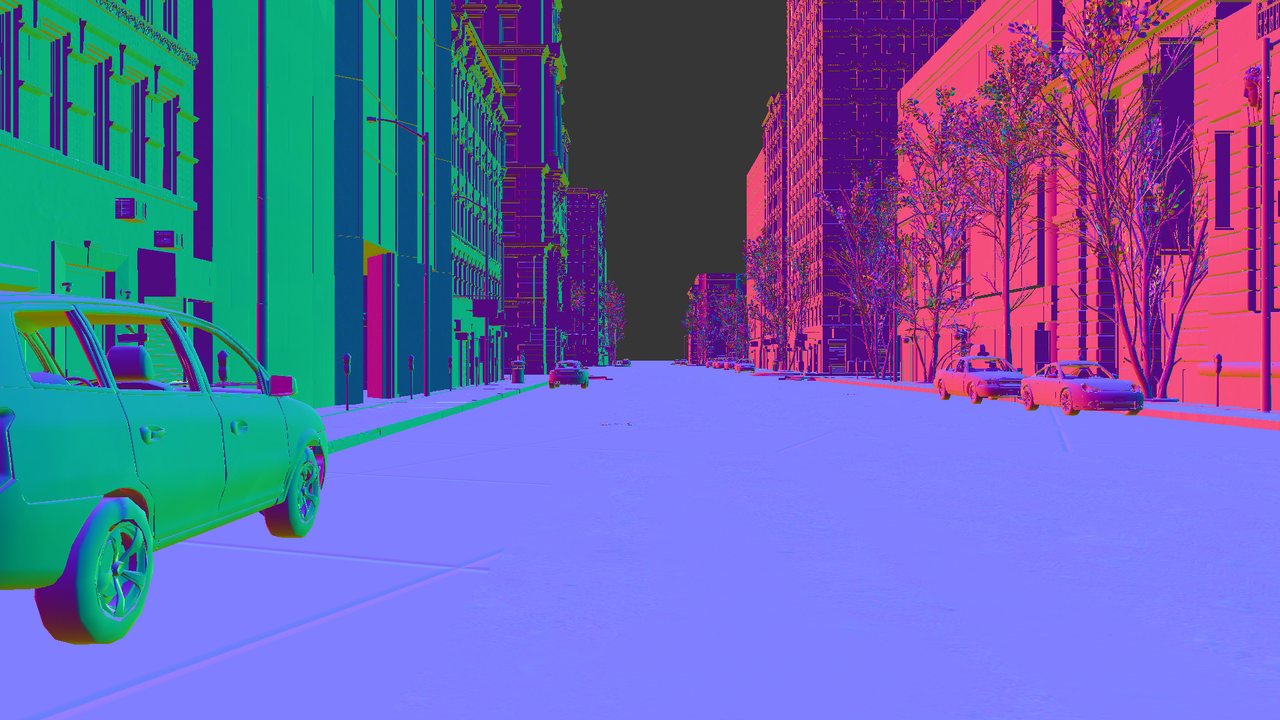
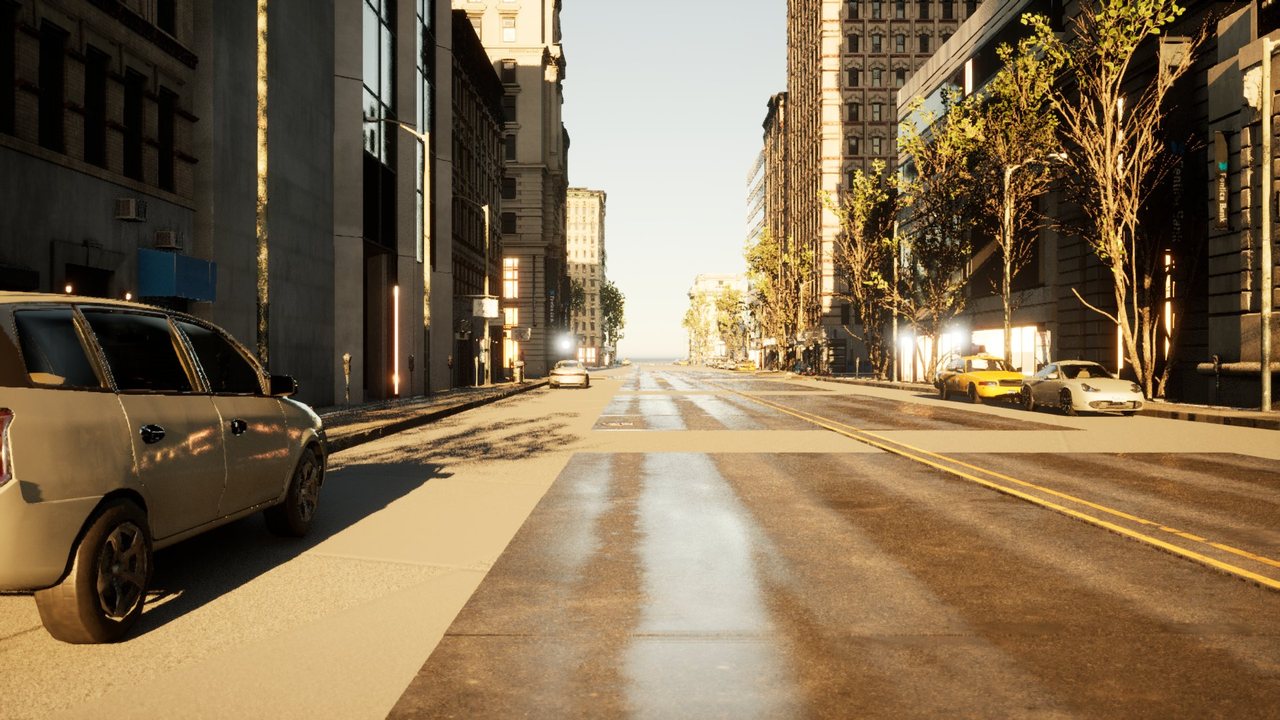
Four layers of one frame from one of our environments. Depth and segmentation colours are a visualisation, not the raw values. Segmentation ground-to-road labels are an estimate.